AI Sales Agents and CRM Data Accuracy: Reading Salesforce's Survey
As of November 2026, the strongest public evidence that AI sales agents improve records is a Salesforce survey of 24 active users [c4], and that is where any business case for ai automation for business should start: the claim is directionally interesting and methodologically narrow at the same time. Salesforce released findings from "The ROI Report: Sales Cloud Agents" on Nov. 10 [c11], based on that survey of active users of Sales Cloud's AI sales agents [c4]. The numbers below come from the report as DemandGen Report summarised it, and they describe what existing users say they experienced, not what a new buyer should expect.
Key takeaways
- Surveyed users said the agents save sellers an average of six hours per week on administrative and research tasks [c1], self-reported by people already using the product.
- 63% said the agents helped deliver more accurate and complete CRM data [c2], the figure most likely to be quoted in a business case and the one that needs the most qualification.
- The average seller spends 60% of their time on non-selling work such as manual CRM updates and account research [c3], the problem the agents are sold against.
- The sample is 24 active users, surveyed online over two days in July 2026 [c4][c12], and the report itself acknowledges the limits of a small group of existing customers.
- Accuracy improves when the write path is governed, not when a model is better. Any ai automation programme starts with a field table, not a demo.
What the survey measured, and over what period
Metric definitions first, because the whole argument turns on them.
The survey population was 24 active users of the agents [c4], not a sample of CRM buyers and not a cross-section of the market. The fieldwork was an online survey conducted over two days in July 2026 [c12]. The report was released on Nov. 10 [c11]. Every percentage in it is therefore a statement about the sentiment of a small group of already-committed customers at one point in time, and none of it is a before-and-after measurement of record quality against a control group.
That distinction matters for a sales-ops lead. A vendor survey of users can tell you what a product feels like to people who adopted it. It cannot tell you how much of the improvement would have happened anyway, or how many buyers tried the same agents and reverted.
The numbers, with the right qualifiers
The headline time figure is that surveyed customers said the agents save sellers an average of six hours per week by taking over individual administrative and research-heavy tasks [c1]. Read it as self-reported time reclaimed, attributed to the product by the people who chose it.
Adoption was strongest in three places: prospecting, account research and CRM pipeline administration, where nearly three-quarters of respondents said they had deployed agents [c5]. Those are the tasks that produce CRM entries in the first place, which is why the data-quality claim sits next to the time figure.
| Reported figure | What it measures | Why it matters for CRM quality |
|---|---|---|
| six hours per week [c1] | Self-reported time saved per seller | Time freed from admin, not verified record improvement |
| 63% [c2] | Respondents saying data became more accurate and complete | Sentiment on quality, not a field-level audit |
| nearly three-quarters [c5] | Share who deployed agents in prospecting, research, pipeline admin | The tasks that create the records |
| 60% [c3] | Seller time spent on non-selling work | The size of the problem the agents address |
The 60% figure comes from earlier Salesforce company research rather than this survey [c3], so it describes the general state of seller time, not the effect of agents. The 63% figure [c2] is the one to be careful with: it is a share of the respondents saying the agents helped, and the report does not define what "more accurate and complete" was checked against.
On deal cycles, with buying committees at eight to 10 people [c6], all customers surveyed said they could handle more leads and accounts with agents than without them [c7], and two-thirds of account executives said deals were moving 10% to 20% faster with agent support [c8]. Both are outcome perceptions, and neither is a record-quality measure.
The leadership picture follows the same pattern: 57% of sales leaders agreed AI agents enabled revenue growth without adding headcount [c9], and 75% said they had kept hiring plans unchanged while increasing total sales output [c10]. These are hiring and growth perceptions, reported by leaders who had already committed to the tools.
The vendor survey problem: who answers, and what they were asked
This survey has a specific shape, and naming it is more useful than arguing about the exact percentages.
It is a post-purchase survey of active users. Everyone in the sample had already deployed the agents, which means the group excludes the buyers who tried them and stopped, the ones whose data got worse, and the ones who never adopted. A survey this size of committed users can credibly say "our users like this". It cannot say "this improves CRM data" for a buyer who has not yet decided.
The fieldwork adds a second limit. An online survey run over two days in July 2026 [c12] is a snapshot of stated experience. Nobody checked the records. There is no field-level completeness rate before and after, no duplicate-count comparison, and no audit of how many agent-written entries were later corrected by a rep.
So the honest reading is this: the survey is evidence that the mechanism can work for users who have wired it in properly. It is not evidence that wiring in an agent is sufficient, and it says nothing about the governance that decides which of those two outcomes a given firm gets.
Where AI automation actually improves CRM data
The accuracy claim survives scrutiny in one specific place: the write path. When an agent takes a conversation, a task or a research step and turns it into a structured record, the quality of that record depends on what the agent is allowed to write, what it does when the source is incomplete, and how a failed write is handled.
A seller who has to log a call after a long discussion will often write a one-line note, or nothing until Friday. An agent that captures the outcome at the moment of the task, against a fixed set of fields, removes the delay and the judgement call about what is worth recording. That is where the six-hour figure [c1] and the 63% figure [c2] plausibly come from. It is also where the same figures can mislead, because the mechanism only holds if the fields are defined, the permissions are narrow and the failure path is tested.
Three conditions decide whether an implementation lands in the "more accurate" camp:
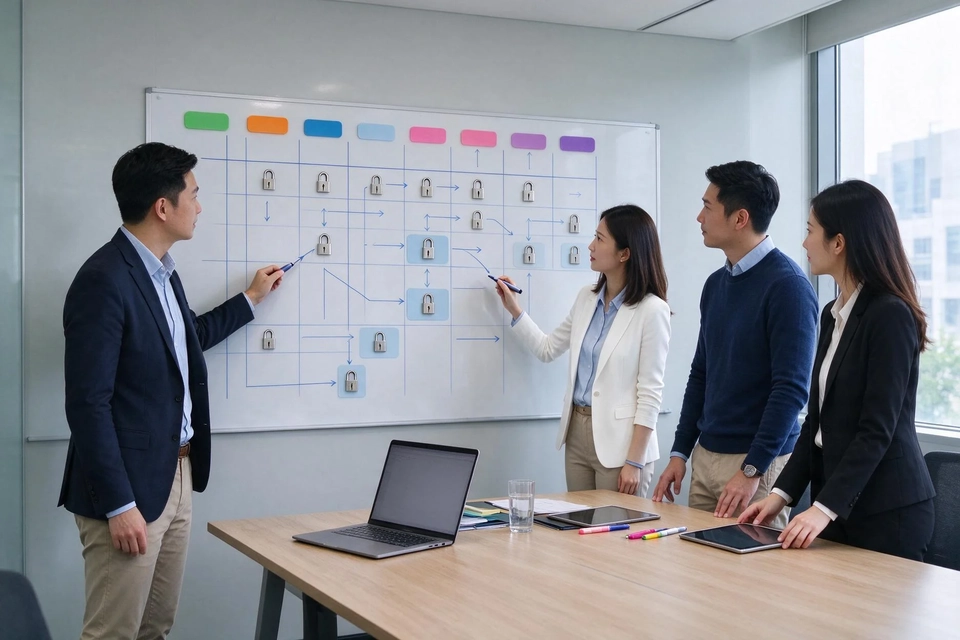
- A field table with owners. Who may write each field, who may overwrite it, and which fields the agent must never fill on its own, usually lifecycle stage, forecast value and anything used in commission.
- Duplicate and failure rules tested before go-live. What the agent does when a write fails, when two records match the same person, and when the source data is missing a required value.
- An acceptance test measured on record quality, not on adoption. Data completeness per required field, the share of agent-written records later corrected, and the ratio of records with no next step are measurable; "the team likes it" is not.
What to fix upstream before you connect an agent
An agent writing into a dirty dataset makes more records, not better ones.
Two things go wrong at the source. First, invalid and duplicate records: an agent that enriches a record which is really three half-records about the same customer will write its output into whichever one it matched. Second, missing values and inconsistent formats: if dates arrive in two conventions and addresses in three, the agent inherits the mess and the reporting downstream inherits it too.
The fix is unglamorous and happens before integration work starts. Invalid records come out, including missing identifiers, malformed contact details and names that are clearly test data. Duplicates get merged so each customer has one record. Missing values are decided per field: imputed, dropped, or flagged for a human. Dates and addresses are standardised, and accuracy is validated against rules or an external source rather than assumed. Skipping this stage is the most common way a promising ai automation pilot ends up producing a bigger pile of the same bad records.
This is also where the pilot design in the Salesforce report quietly matters. The users in the sample had already deployed agents in prospecting, account research and pipeline administration [c5], the tasks that generate records. Firms that connect an agent to a fresh dataset and the same agent to a merged, standardised one will get different answers, and the survey does not tell the two apart.
Who is accountable when an agent writes the record
Accountability is the question the survey never asks, and the one a sales-ops lead has to settle before go-live.
An agent that fills a record is acting in the name of the salesperson and the firm. If it writes a wrong close date, a wrong attribution source or a stage change that never happened, the error lands in reporting, in forecasting and in whatever consumes those fields downstream. The design questions are concrete:
- Is every agent write attributable? A record should show who or what wrote the field and when, so a bad batch can be traced and rolled back.
- Which actions need a human click? Confirming a stage change and overwriting an existing value are the two worth holding behind approval in the first phase.
- What happens when the data is insufficient? The correct behaviour is to raise a confirmation item to the rep rather than infer a value; the control sits in the write rule, not in the model.
- Which fields feed the business? Any field used in forecasts, commission or attribution deserves a stricter rule than a free-text note, because the cost of its error is higher.
A small pilot that writes call outcomes into the customer record and creates a follow-up task is a better first test than a broad deployment. It produces a measurable dataset, it has a narrow failure surface, and it shows within weeks whether agent-written records get corrected. That is also the cheapest way to build a case for ai automation for business that survives a finance review, because the evidence is your own record quality rather than a vendor's survey.
Topkee's view: an agent is an execution layer over the CRM you already have
Topkee builds custom agents on the principle that the CRM stays the system of record and the agent is the layer above it that does the work. In its AI Agent development practice, an existing CRM is treated as a connected business service: interfaces, authorisation, data quality and existing functions are assessed before anything is connected, and reusable connectors are preferred over bespoke writes. That is the "upper execution, lower record" split, and it is the reason Topkee's agent roles are designed around boundaries rather than autonomy.
Care 售前助手 replies in the customer's language, completes opportunity fields with a form the merchant defines, and then invites a human to take over, without storing customer turns or personal data on the assistant side. Cold Call Coach reads the quality of lead data and call-round completion, proposes tasks, and requests approval before any script or strategy change; it does not dial. Leadbox CRM keeps lead status and record consistency current in real time as salespeople work, rather than leaving updates for the end of the week. The automated data integration layer keeps lead status synchronised between systems, and Toxic-data removal and data cleaning handles the upstream merge, missing values and format standardisation that decide whether an agent's writes are worth anything.
None of this is a claim about the Salesforce figures. The knowledge base holds no Salesforce page, no client case and no hours-saved or accuracy figure for these agents, and the comparison is a reading of two architectures, not a benchmark. What it does establish is the division of labour: the CRM vendor owns the field structure and its own agent, and the implementation partner owns the field mapping, the permissions, the write success, the duplicate and failure handling, and the human confirmation when data is missing.
From CRM records to attribution: the downstream test
The record is the input to attribution, and that is the test this article's category cares about.
Stage events drive optimisation. If a stage change is recorded wrongly, a deal marked qualified a week late or a lead moved to "discovered" that never was, the platform signals trained on that event learn the wrong thing. Event feedback only works when sales update stages truthfully and the identifier holding a person's identity across systems stays intact; break either and the join between the CRM and the ad platforms quietly degrades.
One useful measure before you automate the write path: pick a month of closed records and count what share of closed-won deals have a stage history that runs in logical order, with dates that fall inside the deal window. That number is a data-quality reading your own team can produce, and it is a fairer baseline than a vendor's survey of users. If it is low, no agent will fix it on its own; if it is high, an agent has something solid to build on. The same care applies to consent: a field an agent fills from a customer conversation is personal data, and the record it lands in has to obey the consent rules your market sets.
FAQ
Does this mean I should put an AI sales agent in front of my CRM?
Not on the strength of this survey alone. It is evidence that committed users report gains, including six hours per week saved [c1] and 63% reporting more accurate and complete data [c2], drawn from a sample of 24 active users [c4]. Treat it as a reason to run a bounded pilot, not a reason to skip testing.
How reliable is a survey of this size?
It is a sentiment snapshot, not a benchmark. The sample is 24 active users [c4], surveyed online over two days in July 2026 [c12], and everyone in it had already adopted the product. That design measures how a committed group feels; it cannot compare against a control group or count the firms that tried and reverted.
What is the difference between "six hours saved" and "more accurate data"?
Time saved is self-reported and can come from tasks being moved rather than eliminated. Data accuracy would need a field-level measure, such as completeness per required field, duplicates per customer and corrections after the fact, and the report does not publish one. The 63% figure [c2] is respondents saying data improved, which is a starting point for a pilot's acceptance criteria, not the criteria themselves.
Which CRM fields should an AI agent not write?
Lifecycle stage, forecast value and any field that feeds commission or attribution are the ones to hold behind human approval in a first phase. The rule that does most of the work is simpler: when the source data is incomplete, the agent raises a confirmation item instead of filling in customer facts.
How does record quality affect ad measurement?
Stage changes feed optimisation and attribution. If a deal is logged late or an identity identifier breaks, the join between CRM and the ad platforms degrades, and the reporting learns from wrong signals. Measuring stage-history order in a sample month gives you a baseline before automation changes the write path.
Recommended next action
If you are about to connect an agent to a CRM, start with the smaller test: one field group, one approval step, one measurable acceptance criterion. The AI-Driven Google Ads Automation for Marketing Success article picks up where this one stops, on how the same write path feeds ad optimisation, and AI-Powered Google Ads Optimization Strategies covers the measurement side. Before the pilot, write down the ai automation you intend to add, field by field, so the acceptance test has something to compare against.
Sources
- DemandGen Report, "Salesforce: AI Sales Agents Are Improving CRM Data Accuracy, Freeing Reps to Sell", DemandGen Report, 2026-11-13. https://www.demandgenreport.com/industry-news/news-brief/salesforce-ai-sales-agents-are-improving-crm-data-accuracy-freeing-reps-to-sell/55360/