AI Agent Traffic and Your SEO Plan
AI agent traffic changes SEO because a page can now be read by a machine that never sends a visitor, so a business has to make its pages fetchable, keep them fresh, and decide which crawlers may read them. Cloudflare's CEO calls this work "sort of the new version of SEO", and the first ai automation for business budgets that include crawl access are already being set around that idea.
Key takeaways
- Cloudflare and OpenAI made their research pilot public on July 8, 2026, and reported results in October.
- Discoverability used to mean reaching the top of a results page; AI systems now have to find sources, judge them and connect people with the answer.
- Access is a per-crawler decision, and pricing for it exists only in private beta.
- A crawler that re-downloads an unchanged page adds load and brings nothing back, so freshness signals carry a cost argument.
How Agent Traffic Changes the Search Contract
The old contract reads: rank, get the click, keep the visitor. Agent traffic splits that into two events. A crawler fetches the page first, and a person may never follow. Cloudflare's blog of October 2026 puts the shift plainly. Discoverability used to stop at the top of a results page, and the person who visited decided what the page was worth. AI systems now need to find the right sources, understand what is useful and connect people with that information, whether through an answer, a citation or a visit.
The cost of that split sits on the site owner's side. Cloudflare's blog says a crawler that repeatedly downloads an unchanged page adds load without bringing any benefit. Each fetch is bandwidth and server time, paid for whether or not a buyer ever arrives. A page that a human reads once can be fetched again and again by machines checking whether it moved.
That is why crawl behaviour became a budget line rather than an infrastructure detail. It is also why the structure decisions of technical SEO matter to ai automation for business spending: a site that answers crawlers with redirects and near-duplicates pays for the confusion.
What the OpenAI Pilot Actually Showed, and What It Did Not
The pilot set out to test whether signals from Cloudflare's network could help ChatGPT users find new content more efficiently. Both companies announced it on July 8, 2026. Cloudflare's network carries more than 20% of the web, which gives it a live view of how content changes and how traffic behaves.
The published results are narrow in scope and specific in effect.
| What was tested | What Cloudflare reported |
|---|---|
| Network signals for OpenAI's crawler | signals that help the crawler discover more useful pages to surface in ChatGPT |
| Pilot scale | a participating cohort of about 1% of Cloudflare's total network |
| Pages indexed | hundreds of millions of new web pages |
| Who ranks the pages | OpenAI evaluates and ranks independently |
The mechanism is the part worth keeping. A crawler that has to check everything for changes spends its budget on pages that did not move. Cloudflare's blog names the two filters it uses: one keeps crawlers away from pages that do not exist or that redirect elsewhere, and the other, a change signal, tells the crawler when a page is worth another visit. The blog also notes a trade-off. Finding new pages can raise crawling at first while those pages are evaluated, and the aim is to keep discovering while reducing total work.
The blog is careful about outcomes, and so is this article. Cloudflare says it is still working with OpenAI to understand how better site discovery translates into business outcomes. Nothing in the published result says participating sites received more visits, that sites were paid for the signals, or that the signals change ranking rather than discovery. Treat the pilot as an efficiency result.
What a Business Does to Be Found by AI Agents
This is the gap most coverage leaves open, so here is the sequence in order of cost.
Step 1: make the page fetchable. Cloudflare's blog describes how automated traffic can make an empty address look interesting. Bots ask for files that are not there. Some sites send almost any address to the homepage. Other addresses lead to copies of the same content. Fixing those responses before writing new content saves crawl work on every future visit.
Step 2: tell the crawler what changed. A change signal only helps if the site has something accurate to report. If a page's freshness cannot be read, the crawler falls back on re-fetching it. That is the only freshness advice Cloudflare's blog supports, and it is enough reason to keep dates and structure honest.
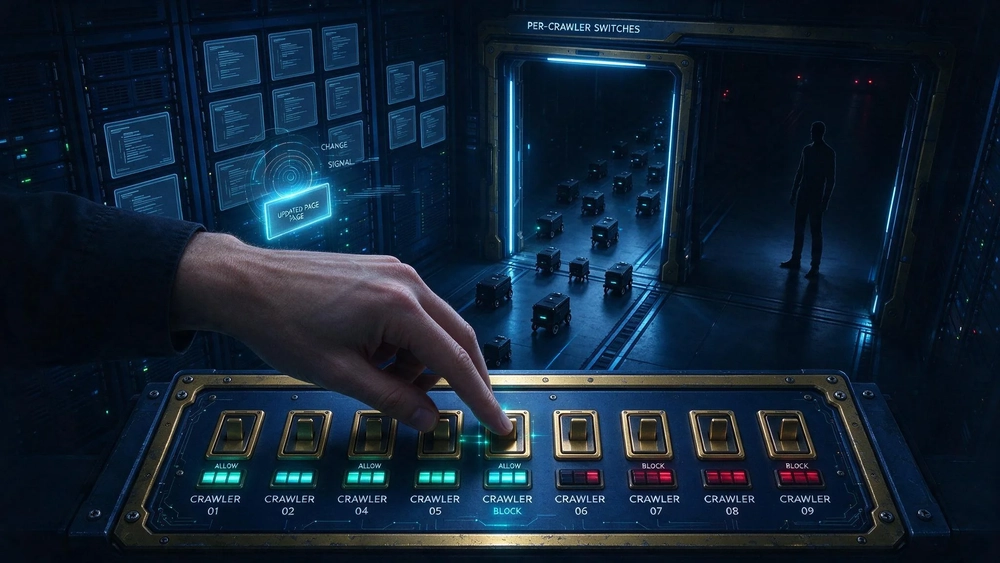
Step 3: decide access per crawler. AI Crawl Control, which Cloudflare makes available on all plans, lets a site see which AI services fetch its content and set allow or block rules for individual crawlers. The documentation names publishers, e-commerce and business sites, and documentation sites as different users of the same tool, and the policies differ for each. For an e-commerce site the policy covers pricing and inventory. Left alone, ai automation work will serve whichever crawler arrives first.
Step 4: make the content worth citing. Discovery only gets a crawler to the page. OpenAI then evaluates and ranks the pages itself, so the page still has to answer the question better than the alternatives.
The access question has a workable test. Name the agents your buyers actually use and let those in. An agent that can send a customer you want is worth allowing, and one that only adds load is not. Anything between the two is a pricing question, and pricing is not available to most sites yet.
Access Control and Pricing Today
AI Crawl Control runs on all plans with no extra contract, so the per-crawler decision is reachable now. The documentation lists what it does: shows which AI services access the content, sets allow or block rules for individual crawlers, tracks robots.txt compliance and which crawlers break it, and offers pay per crawl pricing.
That last item is the productised half of the monetisation story, and it is early. Running the whole set is also basic ai automation housekeeping. Pay Per Crawl, which lets AI crawlers access content by paying per crawl, is in private beta. The direction is settled and the rates are not.
The order of work follows from that. Run the visibility check first, because a site cannot price access it cannot see. Crawler visibility comes before policy, and policy comes before any pricing or discount. A review once a quarter keeps the crawler list current.
Where Automation Fits, and Where It Stops
An ai automation stack built only around content production misses the traffic that arrives without a click. If part of the load is machine traffic, the same team effort should read access data, flag wasted fetches and see which pages agents request without a visit. That work sits next to the reporting the rest of the funnel already needs, such as aligning Google Ads KPIs with business goals and handling AI-driven privacy change in Google Ads.
A useful setup can see crawler activity rather than only page output. A marketer can change access for one crawler without waiting on a developer, and every change carries a written reason.
Topkee's View: Readability First, Access Second
Topkee splits this work into layers, and the company's own position is that none of them is the whole answer.
The visibility layer is the Topkee GEO service, which runs six processes from buyer questions: prompt tracking, query fan-out analysis, sentiment and brand-description analysis, competitor comparison, AI browsing analysis and knowledge-content writing. Its AI browsing analysis covers retrieval sources, cited pages and basic site readability, and it keeps a retrieved source apart from a visible citation in the answer. A marketing lead needs that distinction to know whether a page was read and ignored or never read. The service states its limits as well. Its samples come from an agreed API environment rather than what every consumer sees, and the analysis is not site traffic, so referral and conversion work needs separate website data.
The preparation layer is Topkee AI Agent, positioned as an AI partner for enterprise digital work. It interprets a natural-language task, reads the referenced materials, matches a skill and tools to the task, connects to authorised business services, and returns files, pages and business objects that stay editable. Its connection points are professional method in rules, skills and playbooks, system operation that queries data and acts in the same conversation, and reuse of outputs through the Library. The limit matters: it is a work platform for internal teams and does not make a public site readable to outside agents.
For a Singapore marketing lead, the choice between Topkee AI Agent and a single-purpose content plugin rests on scope, and the plugin work is often the smaller ai automation for business spend anyway. A plugin drafts a page and stops. Topkee AI Agent holds the method in a skill, queries site data in the same conversation and hands back editable pages the team reuses, which suits a team running a quarterly crawler review alongside content output. It does not fetch crawler logs or change edge access rules, so the allow, block and price calls stay with the site's engineers.
The execution layer is technical SEO as Topkee practises it: site architecture, load speed and mobile adaptation, with an audit that covers sitemap, robots.txt availability, redirects, index status and structured on-page settings. Those are the levers that decide whether a crawl signal has something true to report.
What to Check This Quarter
| Check | Question it answers | Decision it forces |
|---|---|---|
| Crawler dashboard | Which AI services fetch the site, and how often | Allow, block or price, per crawler |
| robots.txt health | Whether crawlers follow the directives | Enforce at the edge, not only in the file |
| Fetch quality | How many requests end in redirects, duplicates or empty pages | Fix structure before adding content |
| Freshness | Which pages changed without a date a crawler can read | Add dates where the content moved |
Run the check against one product category first and measure fetches rather than visits. Fetch volume reacts within days. Referral traffic from AI answers moves more slowly and needs its own baseline.
FAQ
Does AI agent traffic replace SEO?
No. It adds a step before the click. Ranking and indexing still decide what a search engine shows, and the pilot's signals affect how quickly a crawler learns that a page changed. The page still has to answer the question.
Should I block AI crawlers?
Block the ones you cannot use. Blocking everything removes any chance of being found through an AI answer, and blocking one crawler that never sends a visitor keeps publishing cost down. AI Crawl Control makes the decision per crawler, so it can be changed later.
What does an AI agent visit cost my site?
Load, not a fee. Each fetch uses bandwidth and server time even when nobody arrives, which is why change signals matter to the site owner. Pay Per Crawl reverses that for content a site chooses to licence, and it is still in private beta.
Can a marketing team do this without a developer?
The content decisions are marketing work. The redirects, robots.txt rules and edge policy usually are not. A workable split has marketing decide which pages matter and which crawlers to allow, with engineering support on the structure.
How do I know agent work is paying off?
Watch fetch volume, blocked requests and the pages agents request repeatedly, then compare those with citation data from AI answers. Traffic alone will not tell you whether a page was read.
Sources
- "Cloudflare CEO Likens AI Agent Optimization To A New Version Of SEO", Search Engine Journal, 2026-11-09. https://www.searchenginejournal.com/cloudflare-ai-agent-optimization-new-seo/596248/
- "Cloudflare Announces Research Pilot with OpenAI", Cloudflare, 2026-07-08. https://www.cloudflare.com/press/press-releases/2026/cloudflare-announces-research-pilot-with-openai/
- "Cloudflare and OpenAI: making AI discovery better for everyone", Cloudflare Blog, 2026-10-15. https://blog.cloudflare.com/cloudflare-openai-discovery-agentic-web/
- "AI Crawl Control", Cloudflare Developer Docs, 2026-08-14. https://developers.cloudflare.com/ai-crawl-control/